

Request access to HUG-VIS
Complete the Hugging Face request, sign the HUG-VIS Dataset Academic Use License, and email the signed agreement from the same official institutional email address. Requests are reviewed manually by the HUG-VIS dataset maintainers.
HUG-VIS is available only to approved applicants for non-commercial academic research under the HUG-VIS Dataset Academic Use License. The Hugging Face requester, responsible applicant, and agreement signatory must be the same eligible individual, and all submitted information must be accurate and complete. After submitting this form, download and sign the agreement and email it from the same official institutional email address. Personal email submissions are not accepted. Access is granted only after manual review by the HUG-VIS dataset maintainers.
Log in or Sign Up to review the conditions and access this dataset content.
HUG-VIS
A Multimodal Benchmark for Human-centered Understanding and Generation in Visual Intelligence
Fei Ma · Zebang Cheng · Minghui Li · Hongbo Xu · Yuyong Tan · Yihua Shao · Hanling Wang · Zhou Liu · Yuqing Gao · Dong Wang · Long Ma · Laizhong Cui · Nicu Sebe · Qi Tian
Guangdong Laboratory of Artificial Intelligence and Digital Economy (SZ) · Shenzhen University · Institute of Automation, Chinese Academy of Sciences · Pengcheng Laboratory · Tongji University · Tsinghua University · The Chinese University of Hong Kong · University of Trento · Huawei

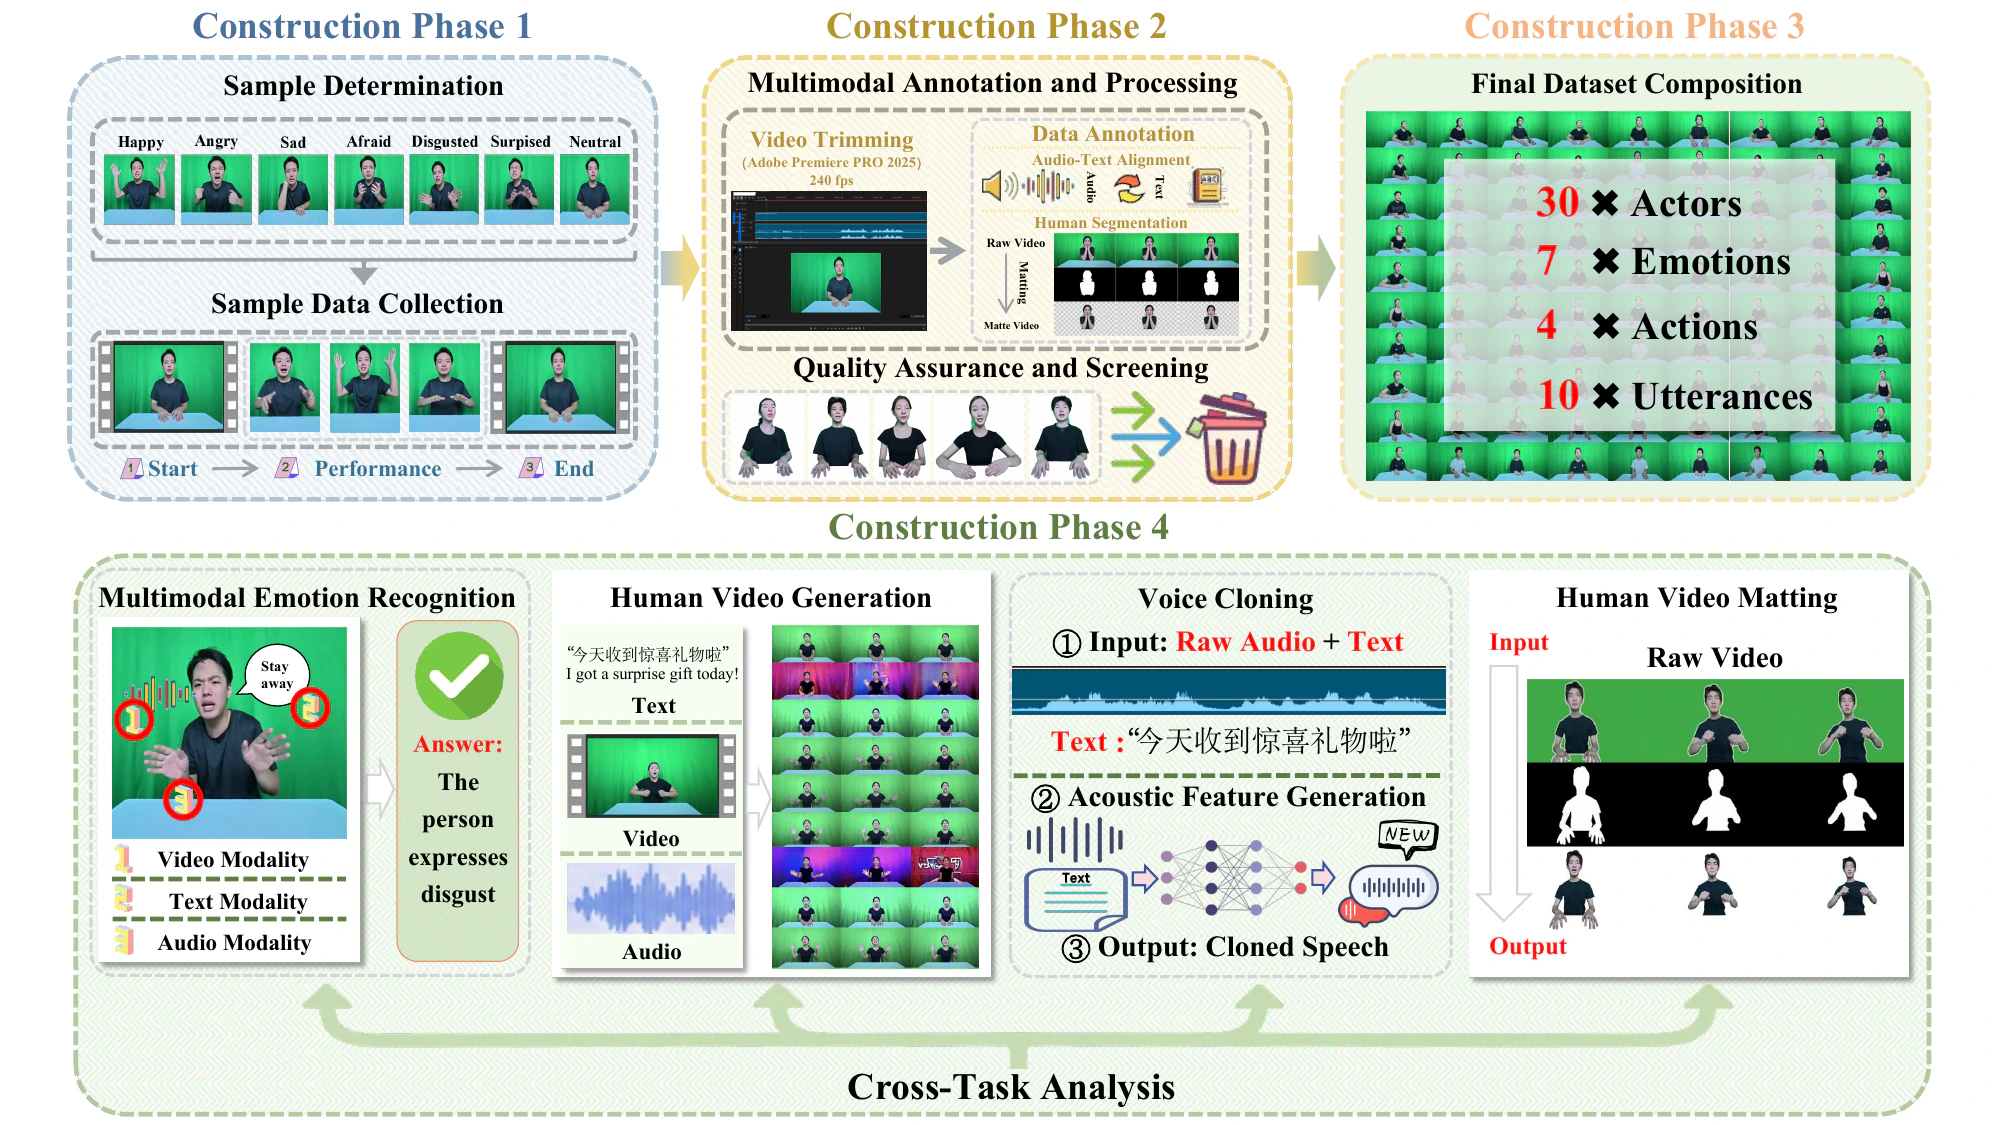
TL;DR: HUG-VIS evaluates multimodal emotion recognition, human video generation, voice cloning, and human video matting on the same condition-aligned grid of 8,400 controlled human performances.
Dataset Access Form
Please follow this format before submitting the gated form. Many requests are rejected because the team information does not match the expected format.
Example Application
| Field | Example |
|---|---|
| Team Name | GML-MMGroup |
| Team Leader Name | Fei Ma |
| Team Leader Official Institutional Email | mafei@gml.ac.cn |
| Team Leader Position / Title | Researcher |
| Hugging Face Username | your-hf-username |
| Team Members (comma-separated) | Fei Ma, Zebang Cheng, Minghui Li |
| Organization / University / Company | Guangming Laboratory |
| Country / Region | China |
- Submit one request per team, not one request per member.
- The request must be submitted by the team leader or main contact person who will also sign the agreement as the responsible applicant.
- Use the same name, institution, position/title, and official institutional email in the online request and signed agreement. Include the exact Hugging Face username in the online request and email subject.
- The responsible applicant must be a faculty member, researcher, or research staff member employed by a university or public/non-profit research institution. Students may not sign as the responsible applicant.
- Personal email addresses are not accepted for the responsible applicant. The signed agreement must be sent from the official institutional email entered in the request.
- Hugging Face grants gated access to the individual account that submits the request. Approval does not automatically grant access to every listed team member, and credentials or access tokens must not be shared.
- Listed research-group members may work with the Dataset only under the responsible applicant's direct supervision, within the approved research environment, and under the same license terms.
Access requests are reviewed manually. Submitting the form does not guarantee approval.
Overview
Human-centered visual intelligence is inherently multimodal: facial expression, body motion, vocal prosody, and linguistic content jointly convey what a person expresses and how that expression is performed. Existing emotion, generation, speech, and matting benchmarks are usually built from different subjects, acquisition conditions, and annotations, making it difficult to compare capabilities or analyze their relationships.
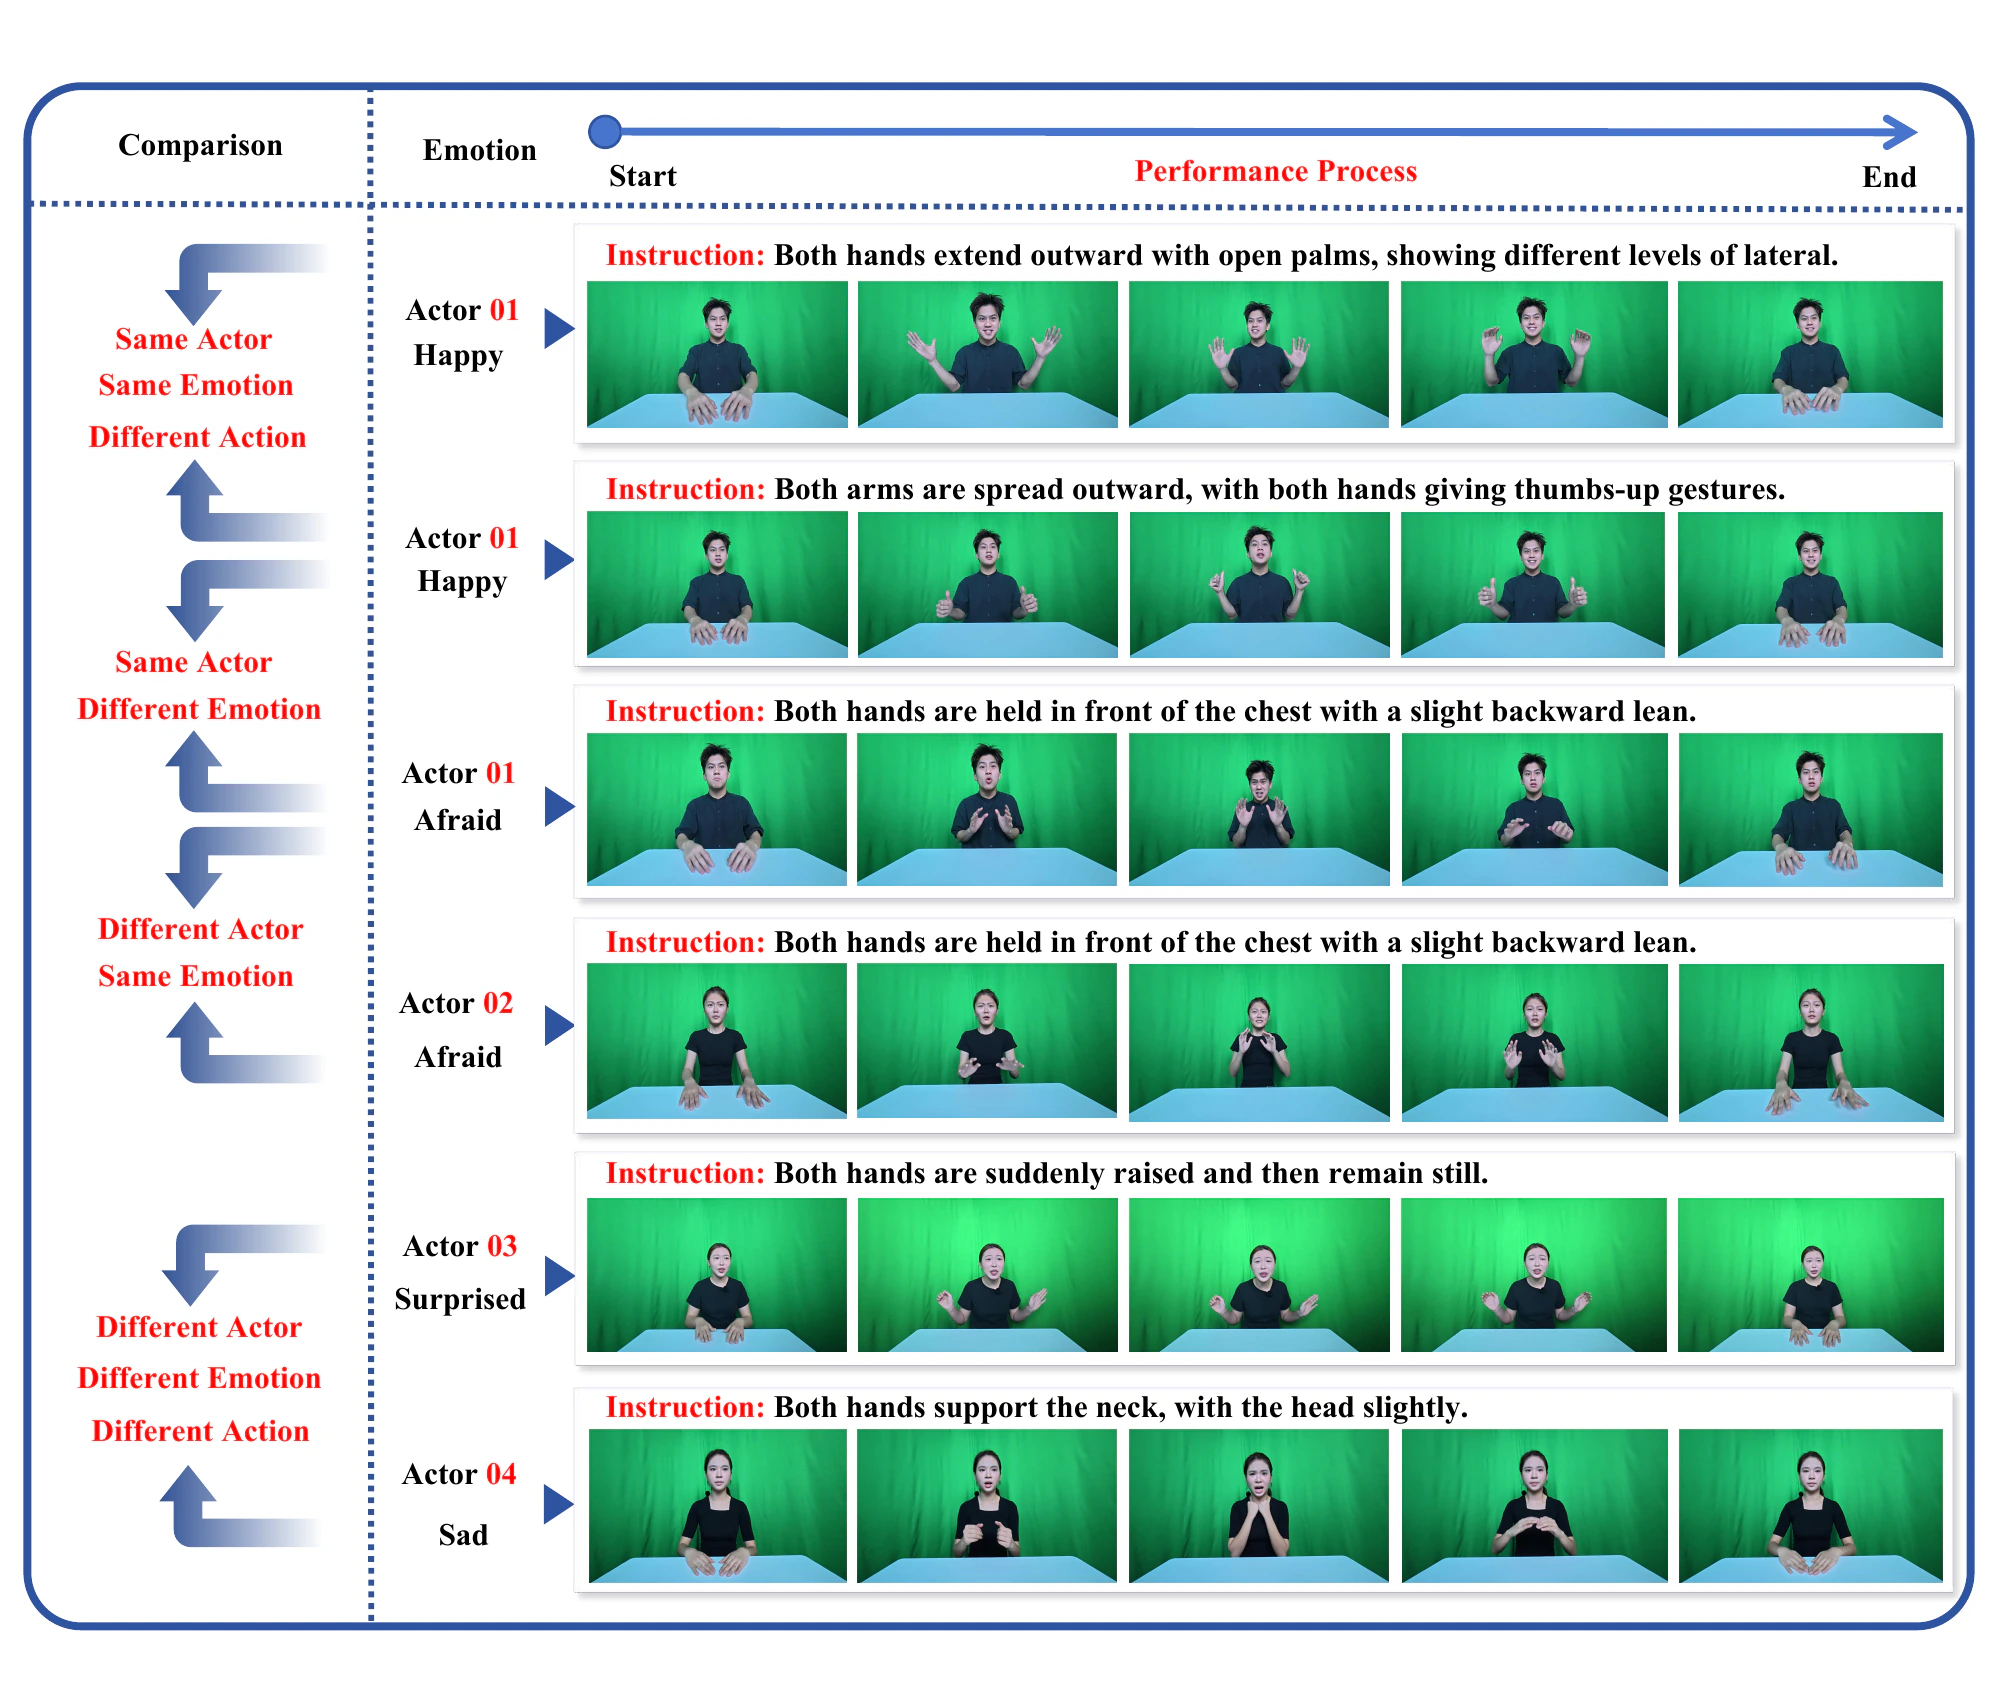
HUG-VIS provides a shared, condition-aligned foundation for both understanding and generation. Thirty professional actors each complete the same 280 emotion-action-prompt assignments under a controlled Mandarin studio protocol. Every performance is packaged with synchronized RGB video, noise-suppressed audio, an assigned Mandarin prompt, a verified transcript, and an alpha-matte sequence.
The benchmark covers four tasks under a common zero-shot protocol:
- Multimodal Emotion Recognition from image, video, audio, text, and multimodal inputs.
- Human Video Generation under audio-driven and vision-driven settings.
- Voice Cloning with speech quality, speaker preservation, and perceptual evaluation.
- Human Video Matting with spatial and temporal alpha-matte evaluation.
Dataset at a Glance
30 actors × 7 emotions × 4 actions × 10 utterances = 8,400 clips
| Property | Value |
|---|---|
| Actors | 30 professional actors; gender-balanced; mean age approximately 20 years |
| Primary spoken and text language | Mandarin Chinese |
| Emotion conditions | Happy, Angry, Sad, Afraid, Disgusted, Surprised, and Neutral |
| Action templates | 4 per emotion |
| Scenario-based utterances | 10 per action; 40 per emotion; 280 per actor |
| Performance clips | 8,400 total; 1,200 per emotion |
| Framing | Controlled, seated half-body capture |
| Video | 1920 × 1080; captured at 240 FPS and released at 30 FPS |
| Audio | Synchronized with video and noise-suppressed |
| Text | Assigned Mandarin prompt and verified transcript |
| Foreground supervision | Alpha-matte sequence |
Each actor performs an identical assignment inventory. This complete actor-by-assignment grid keeps the source material aligned across people and conditions, allowing downstream differences to be attributed more precisely to the actor, model, or evaluation criterion.
The emotion labels represent instructed, acted conditions. They should not be interpreted as the actors' spontaneous emotions, mental states, or clinical affect.
Dataset Composition
Each retained performance includes:
- an RGB video clip;
- synchronized, noise-suppressed audio;
- the assigned Mandarin prompt;
- a verified transcript; and
- a sequence-level alpha matte.
The public repository does not yet document final archive names, split definitions, file extensions, checksums, or the on-disk schema. Users should not infer a file structure from the benchmark description alone.
Data Collection and Quality Assurance
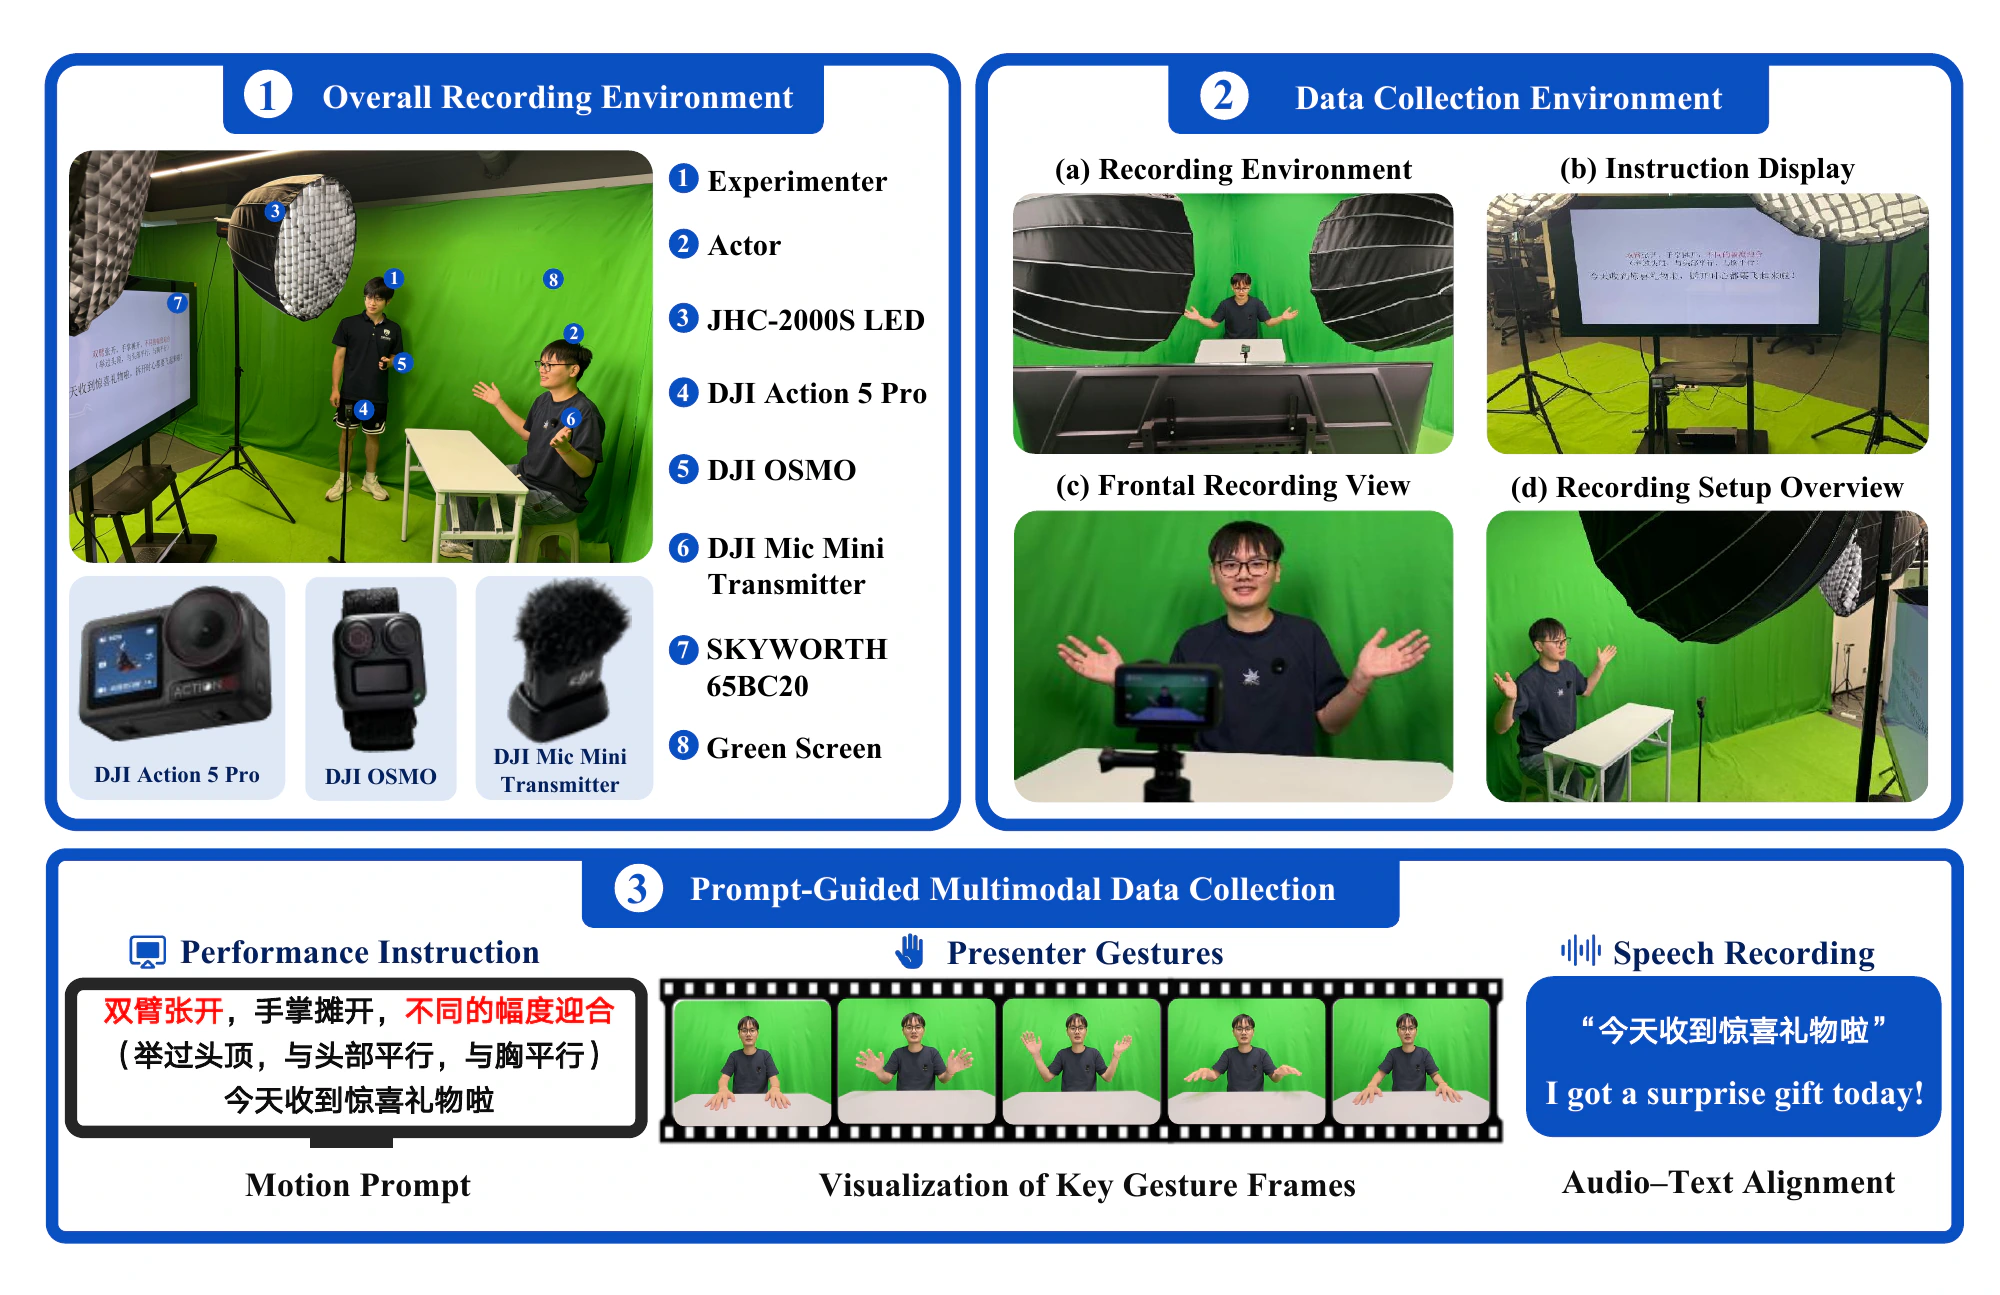
Acquisition Setup
| Item | Specification |
|---|---|
| RGB camera | DJI Action 5 Pro with a fixed frontal mount |
| Background | Uniform green screen for chroma-key matting |
| Lighting | JHC-2000S LED with fixed color temperature and intensity |
| Framing | Seated half-body with a constant subject-camera distance |
| Microphone | DJI Mic Mini transmitter |
| Recording protocol | Rest → prompted performance → return to rest |
The actor begins at rest, delivers the assigned Mandarin prompt together with the corresponding emotion-consistent action, and returns to the resting pose. The shared temporal structure provides consistent boundaries for processing and evaluation while preserving natural variation across actors and performances.
Processing and Quality Control
Alpha mattes are produced in Adobe Premiere Pro through chroma-key initialization followed by sequence-level refinement. Refinement focuses on hair, fingers, clothing, self-occlusion, and motion-blurred regions. RGB, audio, text, and alpha assets are then converted to consistent conventions.
Eight professional volunteers review the retained clips for:
- alignment among RGB video, audio, text, and alpha mattes;
- audio-visual synchronization;
- textual-description and transcript accuracy; and
- segmentation errors caused by motion blur or self-occlusion.
Clips that fail these checks are discarded or returned for reprocessing.
Benchmark Tasks
All reported tasks follow a common zero-shot evaluation protocol: no HUG-VIS benchmark sample is used for training, fine-tuning, calibration, or model selection.
| Task | Inputs / Setting | Evaluation |
|---|---|---|
| Multimodal Emotion Recognition | Image frames, video, audio, text, and multimodal combinations | Seven-class accuracy |
| Audio-driven Human Video Generation | Recorded audio drives animation of a source portrait | CSIM, Sync-C, Sync-D, and MOS |
| Vision-driven Human Video Generation | Visual reference drives head or body animation | LPIPS, CSIM, PSNR, SSIM, FID, and MOS |
| Voice Cloning | Synthesized speech tied to a target actor and compared with reference audio | UTMOS, DNSMOS, speaker similarity, and MOS |
| Human Video Matting | RGB video to alpha matte | MAD, MSE, gradient, connectivity, and dtSSD |
The zero-shot protocol describes the accompanying benchmark evaluation. It does not, by itself, replace the dataset access conditions or define permissions for other research protocols.
Selected Benchmark Findings
- The strongest reported video-audio-text emotion recognition result reaches 83.79% accuracy, while visual-only recognition remains substantially more difficult.
- Human video generation leaders vary across generation regimes, comparison groups, and objective or perceptual criteria.
- Voice-cloning rankings differ between reference-free quality prediction, speaker similarity, and human judgments.
- BiRefNet ranks first among the evaluated matting systems on MAD, MSE, dtSSD, gradient, and connectivity errors.
- Difficulty depends jointly on the instructed emotion, model or capability, and evaluation criterion rather than defining a global emotion ranking.
See the project repository for the latest result tables and cross-task analyses.
Intended Uses
Subject to approval and all applicable access terms, HUG-VIS is intended for:
- non-commercial academic research in multimodal human understanding and generation;
- zero-shot evaluation and comparative benchmarking;
- research on multimodal emotion recognition;
- research on audio-driven or vision-driven human video generation;
- research on voice cloning and speaker preservation; and
- research on spatially and temporally consistent human video matting.
Out-of-Scope and Prohibited Uses
Do not use HUG-VIS to:
- redistribute, mirror, republish, sell, sublicense, or publicly host the dataset, annotations, or restricted derivatives without prior written permission;
- use the dataset or derived files for commercial purposes without prior written permission;
- identify, re-identify, contact, track, impersonate, or harm recorded participants;
- create deceptive deepfakes, defamatory or discriminatory content, sexual content, surveillance systems, or unlawful applications;
- share Hugging Face credentials, tokens, or another user's approved access; or
- publicly release raw or identifiable samples or outputs that reproduce a participant's recognizable face or voice without prior written permission.
Personal and Sensitive Information
HUG-VIS contains identifiable recordings of real human participants, including faces, voices, body movements, and performed expressions. These modalities create risks involving identity inference, impersonation, unauthorized synthesis, and privacy harm.
All actors provided written informed consent before recording for research capture and authorized use of their identifiable likeness, voice, and performed behavior. Public examples released by the project are limited to uses covered by those authorizations; this does not grant dataset recipients permission to republish identifiable material.
Biases and Limitations
- HUG-VIS intentionally prioritizes condition alignment over environmental diversity. Results may not generalize to in-the-wild backgrounds, camera viewpoints, lighting, or recording equipment.
- Capture is fixed-front, green-screen, seated, half-body, and controlled; full-body and unconstrained motion are not represented.
- The actors have a mean age of approximately 20 years. Beyond the reported gender balance, detailed demographic coverage is not provided, limiting population-level or fairness claims.
- The emotion conditions are instructed and acted rather than spontaneous.
- Spoken content, assigned prompts, and transcripts are in Mandarin Chinese; cross-lingual generalization should not be assumed.
- Alpha mattes originate from green-screen chroma key followed by sequence-level refinement rather than an independent physical sensor.
- Quality assurance checks alignment, synchronization, transcript accuracy, and segmentation quality, but no independent emotion-perception validity study is reported.
Request Access and Download
- Read the license. Download and review the HUG-VIS Dataset Academic Use License. Confirm that the proposed work and institution satisfy its non-commercial academic-use terms.
- Submit the Hugging Face request. Sign in to the individual Hugging Face account that should receive access and complete every field in the gated form. Provide the exact Hugging Face username that should receive access.
- Complete and sign the agreement. Enter the same name, institution, position/title, and official institutional email used in the online request. The responsible applicant, signatory, and Hugging Face requester must be the same eligible individual. Students may not sign as the responsible applicant.
- Email the signed agreement. Send it from the official institutional email entered in both forms to Zebang Cheng (
zebang.cheng@gmail.com) and cc Fei Ma (mafei@gml.ac.cn). Use the subject[HUG-VIS Access] Full Name | Institution | HF username. Email the signed agreement. - Wait for review. The HUG-VIS dataset maintainers match the Hugging Face request to the signed agreement and institutional-email submission. If approved, access is granted only to the Hugging Face username named in the application.
After approval, authenticate with the same individual Hugging Face account:
hf auth login
hf download GML-MMGroup/HUG-VIS \
  --repo-type dataset \
  --local-dir HUG-VIS
Inaccurate or incomplete information may lead to rejection. Violations of the approved scope or access conditions may lead to suspension or termination of access.
License and Access Terms
HUG-VIS is not released under a Creative Commons license. It is distributed under the custom HUG-VIS Dataset Academic Use License. The following summary does not replace the signed agreement:
- The Dataset and derived models or materials may be used only for scientific, educational, and non-commercial academic purposes.
- The Dataset, access credentials, annotations, and restricted derivatives must not be sold, transferred, sublicensed, published, uploaded, or otherwise provided to third parties.
- The original video and audio must not be edited, manipulated, composited, dubbed, replaced, or republished as modified source data. Technical processing required for research is permitted only inside the approved research environment; processed copies and new annotations remain restricted.
- Applicants must not identify, re-identify, contact, track, impersonate, or harm recorded participants, or use HUG-VIS for surveillance, deceptive deepfakes, defamation, discrimination, sexual content, or unlawful purposes.
- The Dataset must be stored securely and deleted when the research ends, access is withdrawn, or deletion is requested. Access may be suspended or terminated for any breach.
Citation
The official BibTeX entry and arXiv link will be added when the paper record becomes available.
If you use HUG-VIS, please cite the official paper once the citation is released.
Contact
For dataset access and project questions:
- To: Zebang Cheng —
zebang.cheng@gmail.com - Cc: Fei Ma —
mafei@gml.ac.cn - Project page: https://hug-vis.github.io/#top
- GitHub: https://github.com/GML-MMGroup/HUG-VIS
- Downloads last month
- 94